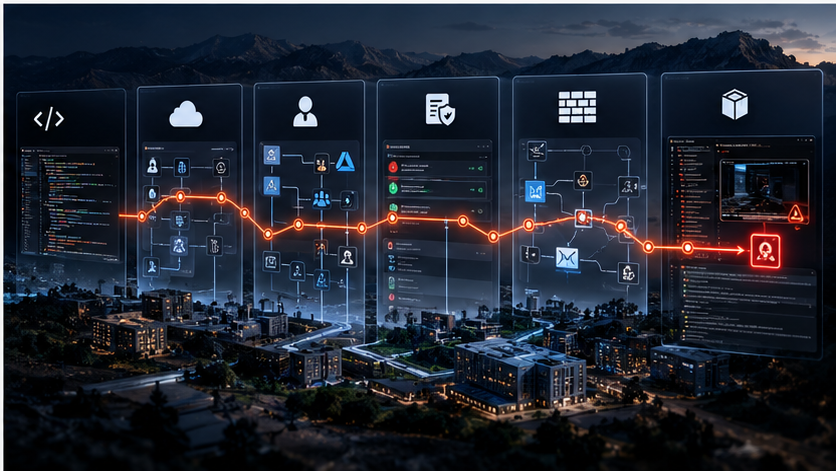
Key takeaway: Autonomous offensive security is attracting serious capital. The durable product is not another alert generator---it is defensible exploit evidence and re-test.
Today, Hadrian announced a $40M round, bringing reported total funding to $65M. In May, XBOW announced another $35M Series C extension. Tenzai continues publishing autonomous offensive-security research.
Sources: - https://hadrian.io/blog/hadrian-40m-raised-to-tackle-the-ai-hacking-cyber-security-crisis - https://xbow.com/news/xbow-secures-additional-35m-from-strategic-investors - https://www.tenzai.com/blog
The signal is clear: autonomous offensive security is becoming a serious software category.
The lazy conclusion is "agents replace pentesters." The more useful conclusion is that the value of a finding is changing.
Finding ≠ proof
Security teams already have findings from SAST, SCA, CSPM, ASPM and DAST.
The scarce output is:
This weakness, in this environment, under these controls and permissions, produces this business impact. Here is the evidence.
That is exploit proof.
Why context gets more valuable
Better models make hypothesis generation cheaper. They do not automatically know the organization's architecture, identity relationships, WAF/network controls, on-prem infrastructure, internal standards, exceptions, tenant boundaries, deployment behavior, failed hypotheses or remediation history.
Two organizations can run the same vulnerable package and have different exploitability.
Use harder benchmarks
Measure: - independently validated findings; - novel chains missed by existing tooling; - false positives after execution; - hypothesis → reproducible evidence time; - fixes successfully re-tested; - unsafe actions blocked by scope; - analyst time per validated path.
A benchmark should punish hallucinated exploitability.
What buyers should demand
Ask to see:
INPUT CONTEXT → HYPOTHESIS → ACTIONS → CONTROL BOUNDARIES → EXPLOIT EVIDENCE → ROOT CAUSE → REMEDIATION → RE-TEST
If the middle is a black box and the end is another severity score, the product has not escaped the scanner model.
The market does not need faster vulnerability spam. It needs faster certainty.
About 0day Factory
0day Factory researches how real attack paths emerge across software, infrastructure, identity, security controls and organizational boundaries.